What a Tripadvisor scraper collects
| Scraper | Input | One result is | Price |
|---|---|---|---|
| Place Details | 1–20 hotel, restaurant or attraction URLs | One place profile | $1.5 / 1,000 results |
| Tripadvisor Reviews | Place URLs, up to 10,000 reviews per place | One review | $0.05 / 1,000 results |
| Search | Up to 20 search terms | One search response with its list of matches | $2 / 1,000 results |
All three export to CSV, JSON or XLSX and run from the web form or the API. The usual order is: find the places, collect their profiles, then pull the reviews you need.
Place profiles: hotels, restaurants and attractions
The Tripadvisor Place Details Scraper takes the URL of a place page, the address that contains Hotel_Review, Restaurant_Review or Attraction_Review, and returns one profile per place. Every profile has the name, Tripadvisor ID, rating, review count, ranking, address, coordinates and the counts behind the rating (how many Excellent, Very good, Average, Poor and Terrible reviews). The other fields depend on the type of place:
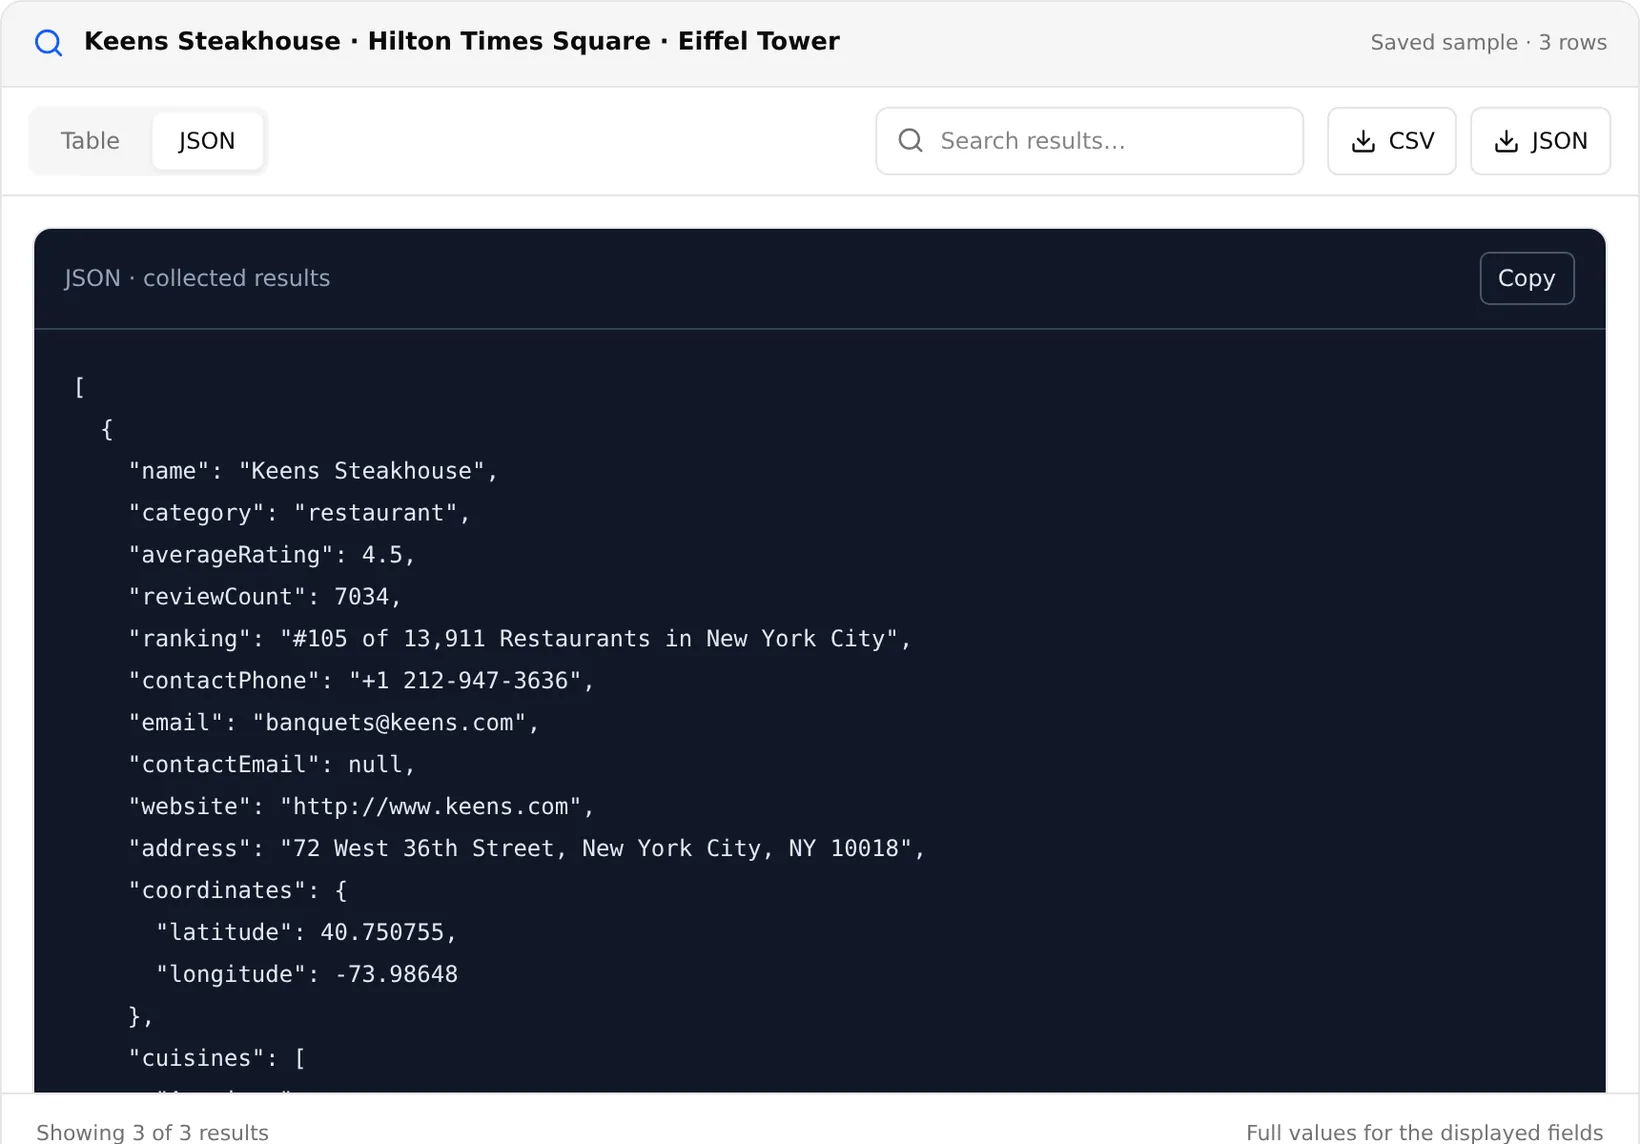
- Restaurants: cuisines, meals served, price level and range, opening hours, dietary options, features such as reservations or a full bar, and sub-ratings for food, service, value and atmosphere.
- Hotels: star rating, amenities, room features and types, languages spoken, sub-ratings for cleanliness, location, rooms, service, sleep quality and value, and price quotes from booking sites captured at collection time.
- Attractions: suggested visit duration, opening hours, nearby restaurants and attractions, and the number of traveller questions and tips.
Phone, website and email come back when the place publishes them. In the saved sample, Keens Steakhouse lists a banquets email while the Hilton hotel lists none, so expect gaps. Each profile also carries the few reviews shown on the place page; for the full review history, use the reviews scraper.
Tripadvisor review scraper
The Tripadvisor Reviews scraper is the Tripadvisor review scraper for bulk work. Paste one or more place URLs and set how many reviews you want per place, up to 10,000. Each row has the rating, title, full text, publication date and review URL, plus language, helpful votes, travel date, trip type, the owner's reply, photos and sub-ratings where the reviewer gave them.
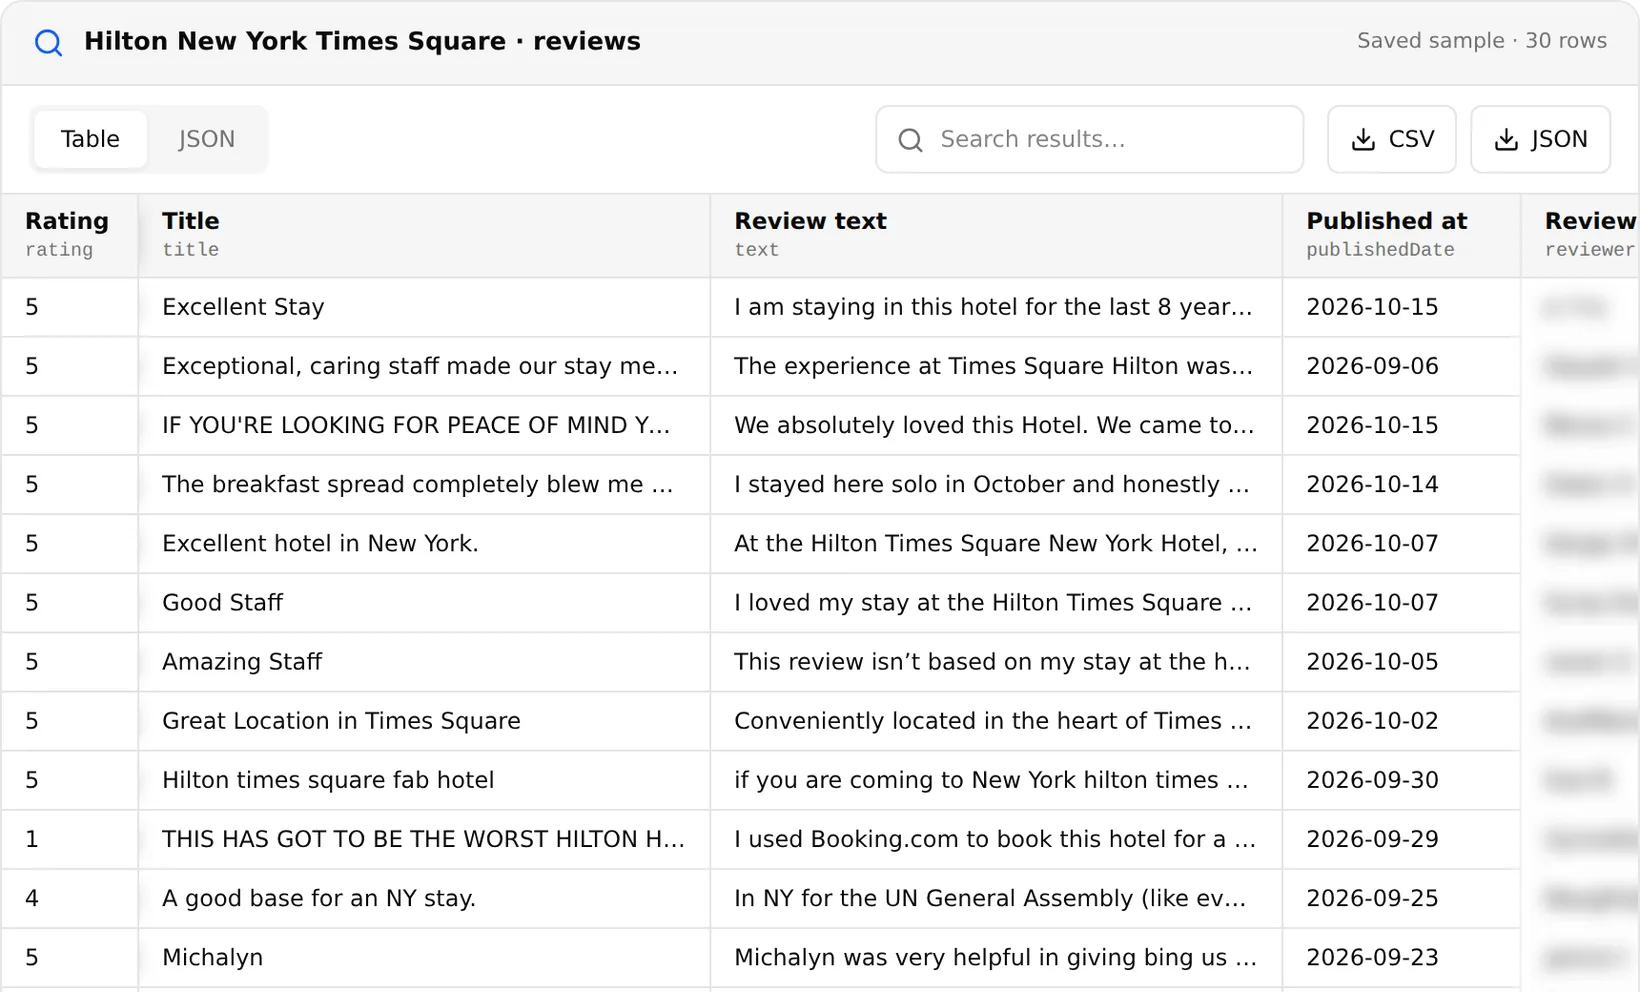
Filters keep the run small. Stop at a date (2026-01-01 or 1 week), keep only certain star ratings, or pick a language. Tripadvisor now serves one review language at a time, so choose one language or all of them. Reviews in other languages arrive in Tripadvisor's English machine translation unless you ask for the original text.
Reviewer details (name, location, profile picture) are personal data. Collect them only when you have a lawful reason; for sentiment and topic analysis the review text and rating are enough. 10,000 reviews cost $0.50.
Finding places with the search scraper
The Tripadvisor Search Scraper works like the search box on Tripadvisor. Give it a name or a phrase such as Keens Steakhouse New York or Paris museums and it returns the matches with their Tripadvisor IDs, names, locations and types. One search term counts as one result, however many matches it returns.
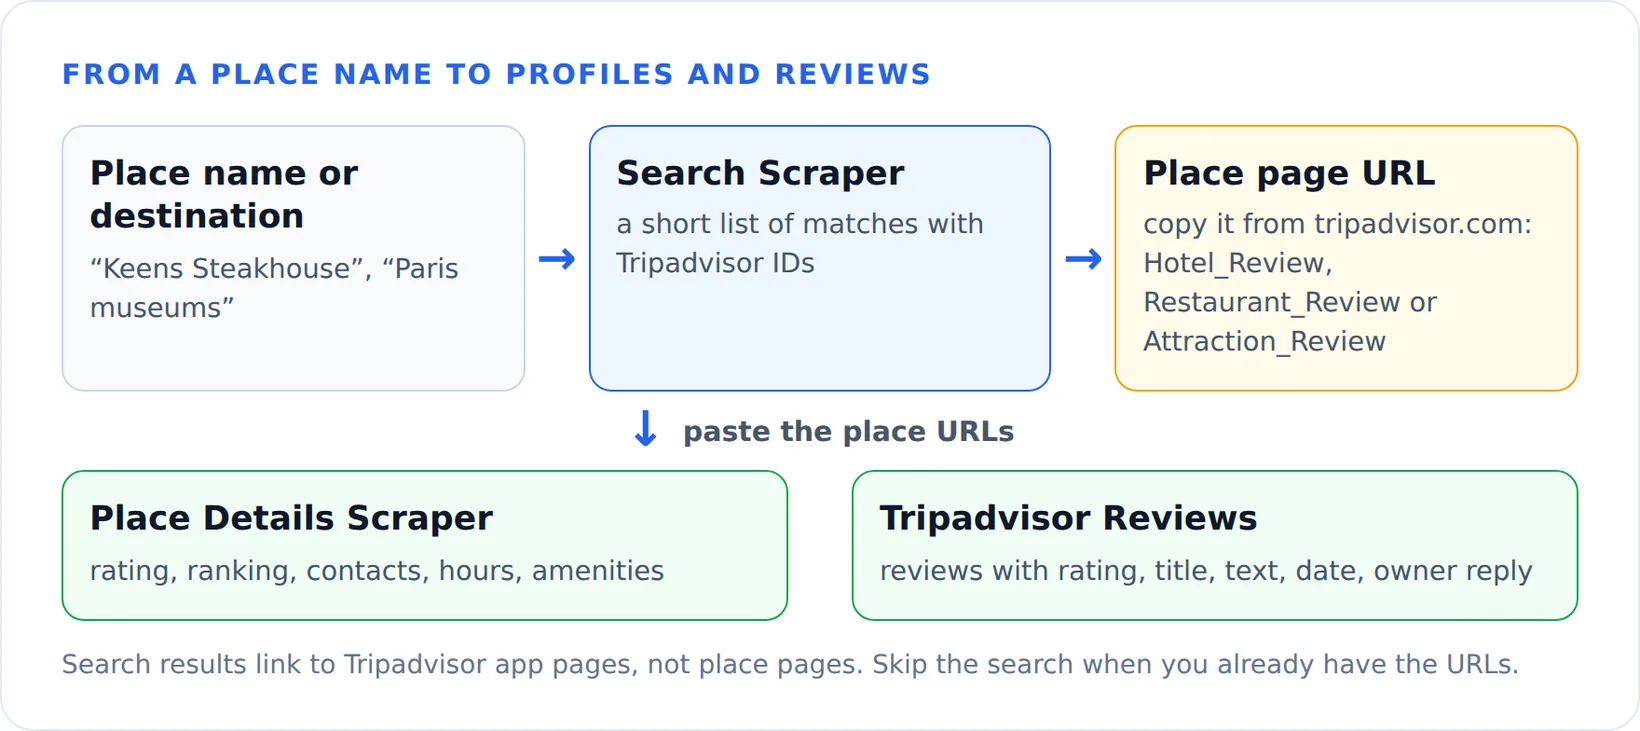
It is a lookup tool, not a city export. In a test search for Paris museums it returned 7 matches, and 6 of them were bookable tours rather than museums. The links it returns open Tripadvisor's app pages, so copy the place page URL from tripadvisor.com before sending it to the details or reviews scraper. Extracto does not export full city listings of every hotel or restaurant from Tripadvisor.
How to scrape Tripadvisor step by step
- Collect the place page URLs: from your browser, from the search scraper or from your own list of competitors.
- Run the Place Details Scraper with up to 20 URLs per task to get ratings, rankings and contacts.
- Run Tripadvisor Reviews on the places whose reviews you need, with a date or rating filter if you only want recent or negative ones.
- Export to CSV or JSON and join the two tables on the Tripadvisor location ID.
Tripadvisor scraper API
Every scraper runs through the Extracto API. This request returns the profile of one restaurant and waits for the result:
curl --request POST 'https://extracto.cloud/api/v1/parsers/tripadvisor-place-details-scraper?wait=1' \
  --header 'X-API-KEY: ext_your_api_key' \
  --header 'Idempotency-Key: ta-keens-2026-11-20' \
  --header 'Content-Type: application/json' \
  --data '{"input": {"detailUrls": ["https://www.tripadvisor.com/Restaurant_Review-g60763-d425330-Reviews-Keens_Steakhouse-New_York_City_New_York.html"]}}'
For reviews, send startUrls with the place URLs and maxItemsPerQuery with the number of reviews per place. The scraper page lists every input and output field.
Tripadvisor's official API
Tripadvisor's legacy Content API is closing down: its documentation says the API is deprecated and that legacy keys would be deprecated on August 31, 2026. The replacement, Terra, has a self-serve Discover plan that is pay as you go. The first 1,000 billable entities are free once per account (not every month); after that the price starts at $0.015 per entity and drops to $0.009 above 5,000 in a billing cycle. Each location returned counts as an entity, and a reviews or photos call counts once per location.
The limits matter more than the price. Terra's reviews endpoint draws from a fixed pool set by your contract (the most recent N reviews or the last M months) and does not search all reviews of a place. Its caching policy does not allow caching, storing or indexing content except the location ID. The API is built for showing live Tripadvisor content in your own app; for analysis you need to keep the data, which is where a scraper fits.
Python and GitHub Tripadvisor scrapers
A Tripadvisor scraper in Python with requests and Beautiful Soup works for a handful of pages, and you will find many Tripadvisor scraper GitHub projects that do exactly that. The trouble starts at volume. Tripadvisor uses bot protection, and in our own tests a scraper that read review pages directly was blocked after the first page. Keeping such code working means proxies, browser rendering and fixes every time the page layout changes. Our web scraping with Python guide covers the basics if you want to try.
A Tripadvisor review scraper Chrome extension, or any point-and-click web scraper for Tripadvisor, exports the page you have open, which suits a one-off check. If you are comparing hosted Tripadvisor scrapers, compare the price per 1,000 reviews, the number of reviews you can get per place, and whether failed runs are charged.
What people use Tripadvisor data for
- Hotel and restaurant benchmarking: ratings, rankings and sub-ratings for your property and its competitors, refreshed monthly.
- Reputation reports: new reviews since the last report, low ratings first, with the owner's reply status.
- Guest feedback analysis: topics and sentiment across thousands of reviews, split by trip type or language.
- Travel research: attractions and restaurants in a destination, with visit durations and opening hours.
- Wider coverage: combine with Google reviews and Yelp. Tripadvisor is strongest for hotels, attractions and travellers' restaurants; Yelp and Google cover more local services.
For hotels, Booking.com reviews split praise from complaints: see the Booking.com API guide.
Is it legal to scrape Tripadvisor?
Place profiles and reviews are public, but Tripadvisor's terms restrict automated access and reviewers are people whose names are personal data. Leave reviewer details off unless you need them, use reviews for analysis rather than republishing them on your site, and use the official API when you want to display Tripadvisor content to your users.